原题目
进入这个网站:点击访问,获取排行榜中所有电影的相关数据(具体字段参考下面的要求明细),并存入指定数据库中。
要求如下:
1. 数据库信息:IP:43.143.30.32 端口号:3306 用户名:yingdao 密码:9527 库名:ydtest 表名:movies(注意,该数据库只开放了写入权限,无法查询)
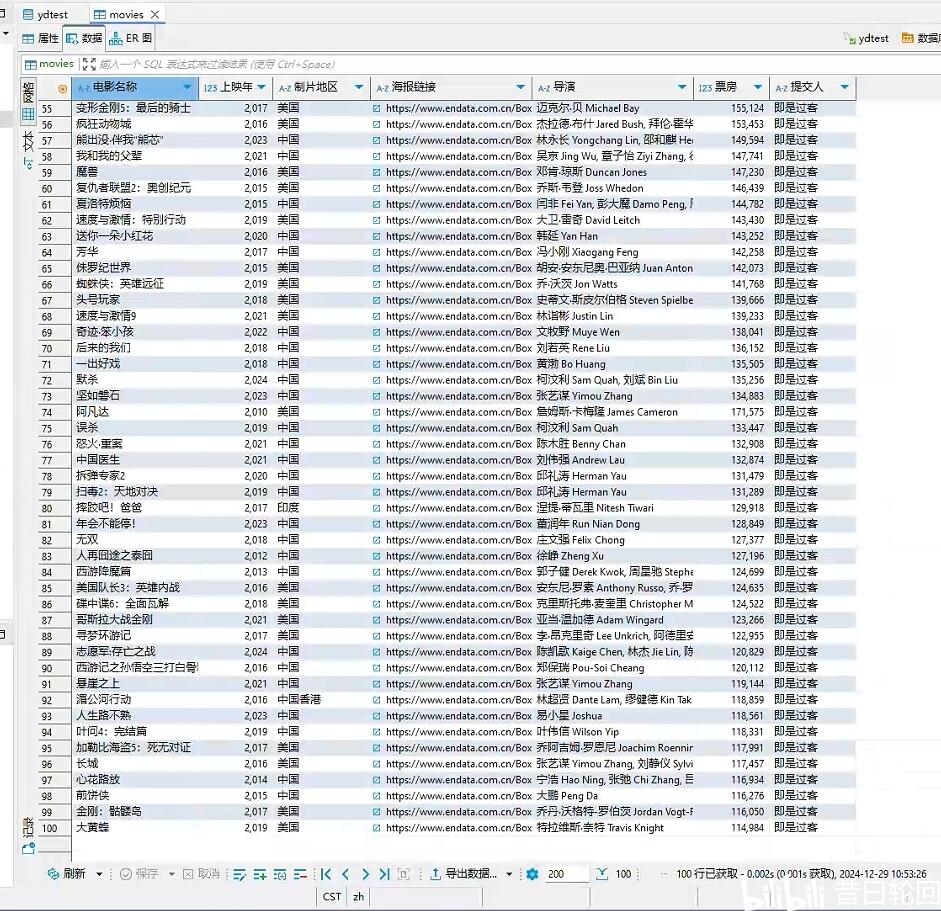
2. 字段及数据格式参考(多名导演用英文逗号分隔开,提交人为影刀学院用户名!位于学院首页右上角):
3. 元素对象都要使用xpath表达式获取(禁止使用【批量数据抓取】指令)
4. 使用编码版完成所有操作
5. 该网站具备反爬虫机制,频繁发送请求可能导致访问被禁止
测试结果
Python代码
# 使用提醒:
# 1. xbot包提供软件自动化、数据表格、Excel、日志、AI等功能
# 2. package包提供访问当前应用数据的功能,如获取元素、访问全局变量、获取资源文件等功能
# 3. 当此模块作为流程独立运行时执行main函数
# 4. 可视化流程中可以通过"调用模块"的指令使用此模块
# 使用方法
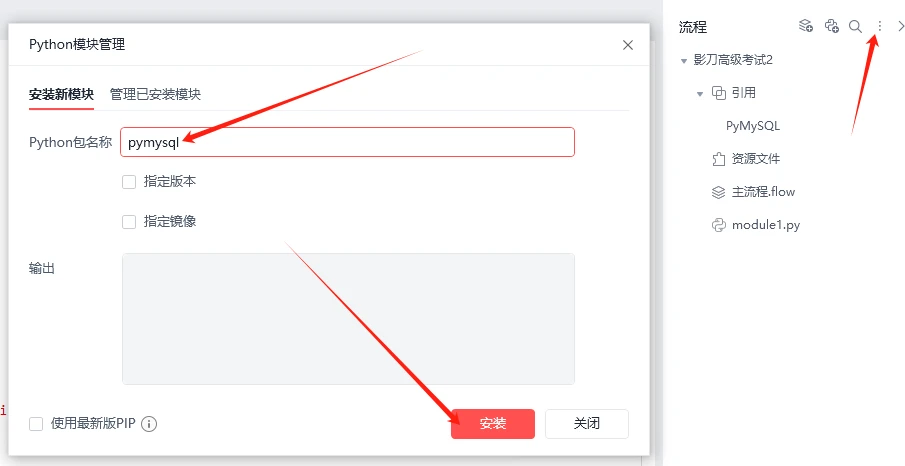
# 安装pymysql包
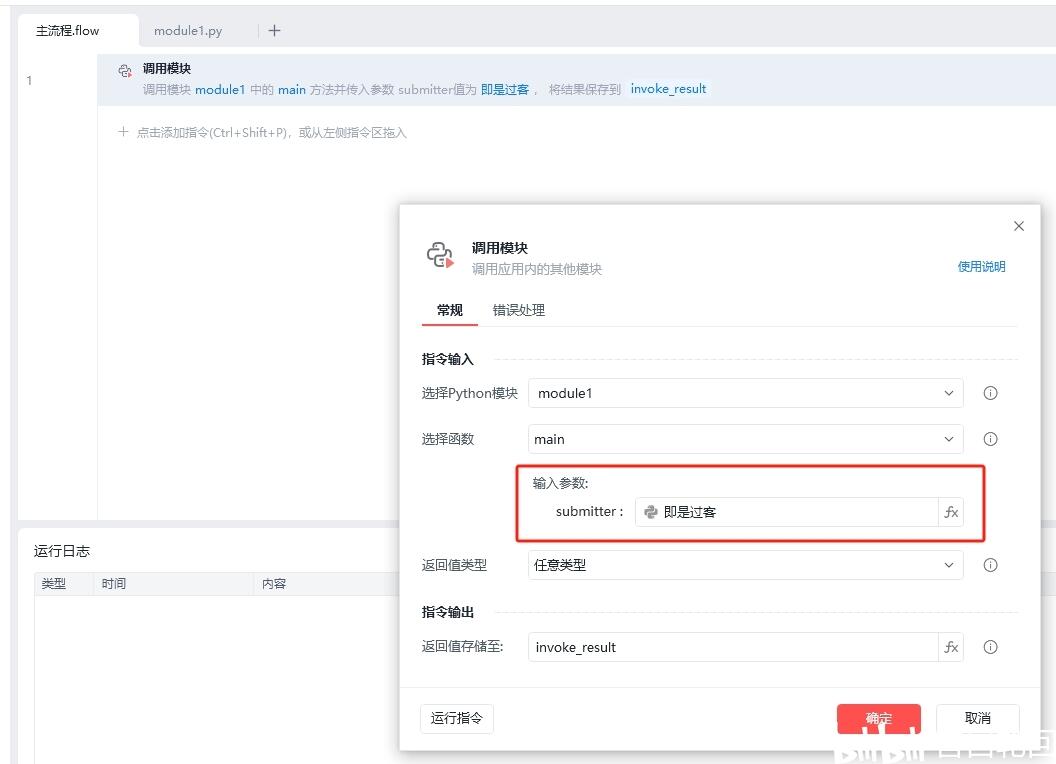
# 主流程使用“调用模块”指令,选择Python模块,选择函数“main”,传入参数submitter(影刀学院用户名),执行即可
# 题目中的网站具备反爬虫机制,不建议访问过快,可在代码最后一行调整随机停顿时间范围
分享链接:https://hyk416.cn/archives/HqnEUzAW
# GuoKe - 过客
# 2024-12-28 9:59:04
import xbot
from xbot import print, sleep
from .package import variables as glv
import time
import pymysql
import re
from xbot import web
import random
def get_directors(web_dg):
"""获取导演信息,如果有多个导演,使用英文逗号分隔"""
directors = []
try:
director_elements = web_dg.find_all_by_xpath('//dt[text()="导演"]/following-sibling::dd[not(preceding-sibling::dt[text()="演员"])]')
for element in director_elements:
if element and element.get_text():
directors.append(element.get_text().strip())
except Exception as e:
print(f"获取导演信息时发生错误: {e}")
return ', '.join(directors)
def format_data(data):
"""格式化数据以符合数据库字段类型"""
name, release_year, production_area, poster_link, director, box_office, submitter = data
# 转换数据类型
try:
release_year = int(release_year)
except (ValueError, TypeError):
release_year = 0 # 或者其他默认值
# 处理票房单位
if isinstance(box_office, str):
box_office = box_office.strip()
if '万' in box_office:
box_office = box_office.replace('万', '')
try:
box_office = round(float(box_office), 0) # 四舍五入到整数
except (ValueError, TypeError):
box_office = 0 # 或者其他默认值
elif '亿' in box_office:
box_office = box_office.replace('亿', '')
try:
box_office = round(float(box_office) * 10000, 0) # 四舍五入到整数
except (ValueError, TypeError):
box_office = 0 # 或者其他默认值
else:
try:
box_office = round(float(box_office.replace(',', '')), 0) # 四舍五入到整数
except (ValueError, TypeError):
box_office = 0 # 或者其他默认值
else:
box_office = 0 # 如果不是字符串,默认设置为0
return (name, release_year, production_area, poster_link, director, int(box_office), submitter)
def main(submitter):
mydb = None
mycursor = None
web_page = None
web_dg = None
try:
# 创建数据库连接
mydb = pymysql.connect(
host="43.143.30.32",
port=3306,
user="yingdao",
password="9527",
database="ydtest",
charset='utf8'
)
mycursor = mydb.cursor()
# SQL插入语句,使用参数化查询
sql = """
INSERT INTO movies (电影名称, 上映年份, 制片地区, 海报链接, 导演, 票房, 提交人)
VALUES (%s, %s, %s, %s, %s, %s, %s)
"""
# 打开首页
web_page = xbot.web.create(url="https://www.endata.com.cn/BoxOffice/BO/History/Movie/Alltimedomestic.html")
random_sleep()
while True:
# 获取当前页的所有电影链接
quanbu = web_page.find_all_by_xpath('//tbody/tr/td/a')
if not quanbu:
print("未找到电影链接")
break
for dys in quanbu:
if not dys:
continue
movie_url = 'https://www.endata.com.cn' + dys.get_attribute('href')
web_dg = xbot.web.create(url=movie_url)
random_sleep()
try:
name_element = web_dg.find_by_xpath('//div[@class="rbox1"]/h3')
if not name_element:
print("未找到电影名称")
continue
name = name_element.get_text()
director = get_directors(web_dg)
box_office_element = web_dg.find_by_xpath('//p[text()="累计票房"]/following-sibling::strong')
if not box_office_element:
print("未找到票房数据")
box_office = ''
else:
box_office = box_office_element.get_text().strip()
poster_link = movie_url
year_element = web_dg.find_by_xpath('//div[@class="rbox1"]/h3/sub')
if not year_element:
print("未找到上映年份")
release_year = ''
else:
release_year = re.search(r'\d+', year_element.get_text()).group() if re.search(r'\d+', year_element.get_text()) else ''
area_element = web_dg.find_by_xpath('//*[@id="Minfo"]/div[2]/div[2]/div[2]/p[5]')
if not area_element:
print("未找到制片地区")
production_area = ''
else:
production_area = area_element.get_text().lstrip("国家及地区:")
data = (name.split("(")[0], release_year, production_area, poster_link, director, box_office, submitter)
formatted_data = format_data(data)
# 插入数据到数据库
try:
mycursor.execute(sql, formatted_data)
mydb.commit()
print("数据插入成功:", formatted_data)
except Exception as e:
mydb.rollback()
print(f"发生错误: {e}, 数据: {formatted_data}")
finally:
if web_dg is not None:
web_dg.close() # 关闭当前电影详情页
# 尝试点击下一页按钮
next_page_btn = web_page.find_by_xpath('//a[@class="layui-laypage-next"]')
if next_page_btn and 'layui-disabled' not in next_page_btn.get_attribute('class'):
next_page_btn.click()
random_sleep() # 等待新页面加载
else:
# 如果下一页按钮不存在或已禁用,则停止循环
print('未找到下一页元素,结束执行')
break
except Exception as e:
print(f"主函数运行时发生错误: {e}")
finally:
# 关闭数据库连接
if mycursor is not None:
mycursor.close()
if mydb is not None:
mydb.close()
# 确保关闭所有打开的浏览器窗口
if web_page is not None:
web_page.close()
web.close_all('cef') # 确保所有CEF浏览器实例都被关闭
def random_sleep():
"""生成5到10秒之间的随机等待时间,应对一下反扒机制"""
sleep(random.uniform(5, 10))
使用方法
添加Python包 pymysql
主流程 调用模块main 传入参数影刀用户名 运行即可